~/work/parallel-convolution/README.md
Parallel Multi-Kernel Convolution
Making the core of a CNN layer up to 98× faster with threads, SIMD and better memory access.
Problem
A convolutional layer applies many filters across an input with many channels. The supplied reference loops over filters, positions, channels and kernel coordinates one multiply at a time, so large layers take minutes.
Approach
- Parallelise over filters. Each output filter is independent, so
#pragma omp parallel forhands whole filters to threads with no shared writes. - Vectorise the inner loop. 128-bit SSE intrinsics (
_mm_loadu_ps,_mm_mul_ps) compute four products at a time, then widen to double precision (_mm_cvtps_pd,_mm_hadd_pd) so the result still matches the reference. - Fix the memory access. Each worker repacks its integer kernel into a channel-contiguous float layout, so the innermost loop walks memory sequentially instead of striding.
- Trust, but verify. The harness times both versions and sums the absolute difference between outputs on every run.
A note on the numbers
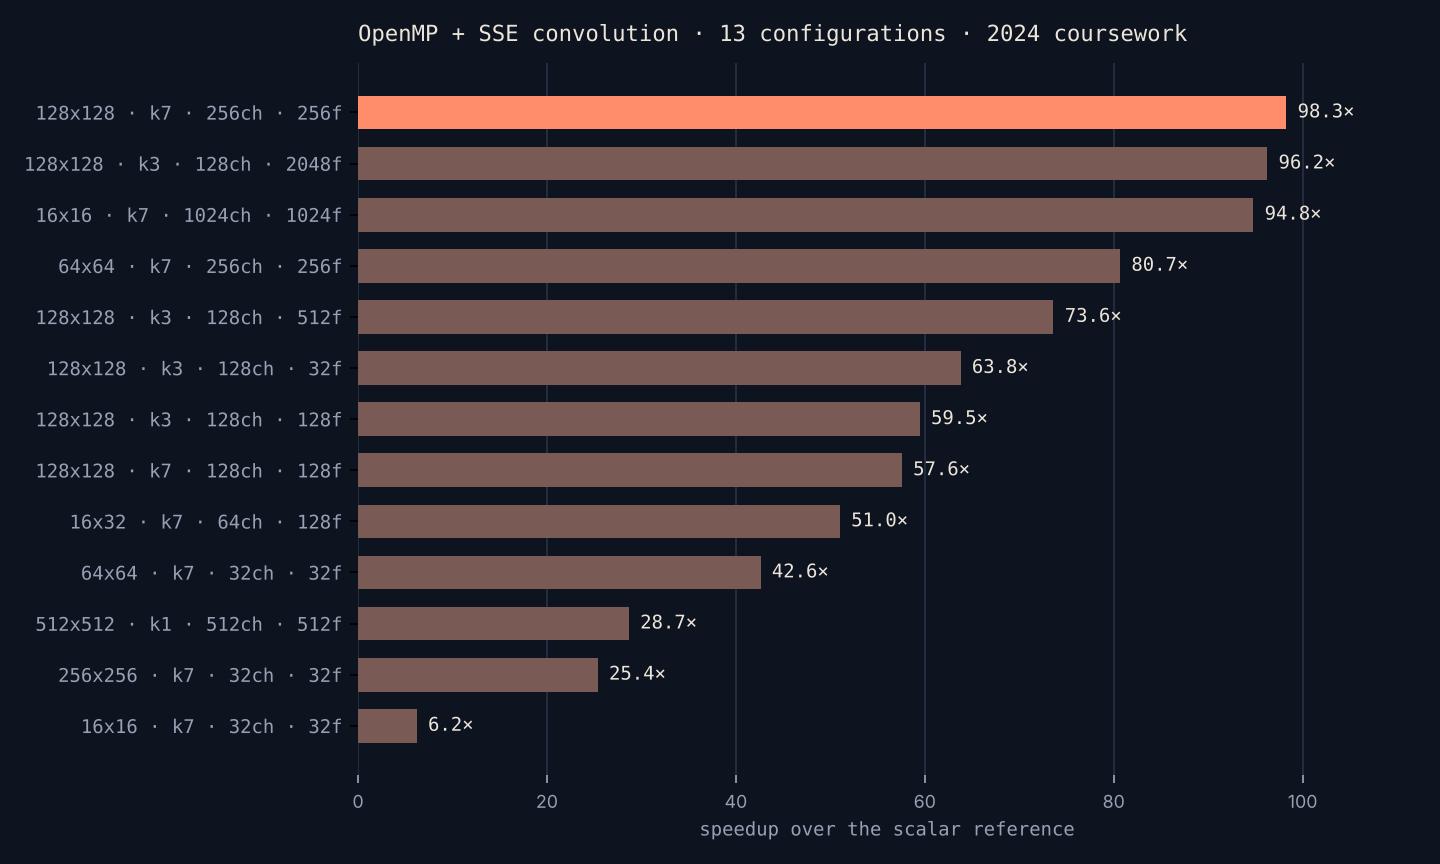
These are measurements from our 2024 report, on Trinity’s shared multicore server. Thread count, machine load and compiler flags all move the result, so treat them as what we observed, not a guarantee.
~/architecture
- image[w][h][c] · kernels[f][c][k][k]
- #pragma omp parallel for over filters
- repack each kernel channel-contiguous
- SSE: 4 float products per step
- double-precision accumulate + check vs reference
~/results
98.3×
peak speedup (128×128 image, 7×7 kernels, 256 channels, 256 filters)
6.2×
on the smallest input, where threading overhead dominates
13
configurations benchmarked against the scalar reference
=
output checked against the reference on every run
~/figures